aix平台Oracle数据库由于断电无法启动故障处理

一套运行在aix环境的的10.2.0.4 rac库,由于异常断电导致数据库无法正常启动,报错为ORA-00600 6101。alert日志报错如下

Tue Oct 13 18:32:04 2026
ALTER DATABASE OPEN
This instance was first to open
Tue Oct 13 18:32:04 2026
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Tue Oct 13 18:32:08 2026
Started redo scan
Tue Oct 13 18:32:08 2026
Completed redo scan
 2573 redo blocks read, 396 data blocks need recovery
Tue Oct 13 18:32:08 2026
Started redo application at
 Thread 2: logseq 61170, block 1720185
Tue Oct 13 18:32:08 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Tue Oct 13 18:32:08 2026
RECOVERY OF THREAD 2 STUCK AT BLOCK 63042 OF FILE 3
Tue Oct 13 18:32:08 2026
RECOVERY OF THREAD 2 STUCK AT BLOCK 38304 OF FILE 3
Tue Oct 13 18:32:08 2026
Errors in file /oracle/admin/orcl/bdump/orcl1_p001_123772.trc:
ORA-00600: internal error code, arguments: [6101], [16], [728], [32], [], [], [], []
Tue Oct 13 18:32:08 2026
Hex dump of (file 3, block 61217) in trace file /oracle/admin/orcl/bdump/orcl1_p013_254256.trc
Corrupt block relative dba: 0x00c0ef21 (file 3, block 61217)
Bad header found during crash/instance recovery
Data in bad block:
 type: 6 format: 1 rdba: 0x000000c0
 last change scn: 0x4f2b.ef213393 seq: 0xd flg: 0xe1
 spare1: 0x20 spare2: 0xa2 spare3: 0x41c5
 consistency value in tail: 0x00004f2b
 check value in block header: 0x104
 block checksum disabled
Reread of rdba: 0x00c0ef21 (file 3, block 61217) found same corrupted data
 from side 
Reread of rdba: 0x00c0ef21 (file 3, block 61217) found same corrupted data
 from side 
………………一直循报file 3 block 61217坏块错误

对于这种情况,尝试人工recover datafile文件

SYS@orcl1>recover datafile 1;
Media recovery complete.
SYS@orcl1>recover datafile 2;
Media recovery complete.
SYS@orcl1>recover datafile 4,5,6,7,8,9;
ORA-00283: recovery session canceled due to errors
ORA-12805: parallel query server died unexpectedly


SYS@orcl1>recover datafile 4;
Media recovery complete.
SYS@orcl1>recover datafile 6,7,8,9;
Media recovery complete.
SYS@orcl1>recover datafile 10,11,12,13,14;
ORA-00279: change 15260723994623 generated at 12/10/2024 06:52:06 needed for thread 2
ORA-00289: suggestion : /oracle/db10g/dbs/arch/2_61129_726871555.dbf
ORA-00280: change 15260723994623 for thread 2 is in sequence #61129


Specify log: {<RET>=suggested | filename | AUTO | CANCEL}
cancel
Media recovery cancelled.
SYS@orcl1>recover datafile 10,11,12,14;
Media recovery complete.
SYS@orcl1>recover datafile 15,16,17,19,20,21,22,23,24,25;
Media recovery complete.
SYS@orcl1>recover datafile 26,27,28,29,30,32,31;
Media recovery complete.

这里有几个文件没有recover 成功,有些是坏块,有些是缺少归档,对于这种情况一般有两种处理思路:
1. 通过屏蔽一致性,强制把库拉起来
2. 通过bbed修改文件头,然后直接正常open库,这里我们选择了第二种方法,把异常的几个数据文件头状态修改和file 1的一样(这里为什么没有使用obet(Oracle Block Editor Tool),不是obet没有这个功能,是由于obet我没有在aix平台进行编译)

BBED> set file 1
        FILE#           1

BBED> p kcvfh.kcvfhckp
struct kcvfhckp, 160 bytes                  @484     
   struct kcvcpscn, 8 bytes                 @484     
      ub4 kscnbas                           @484      0x3393501d
      ub2 kscnwrp                           @488      0x0de1
   ub4 kcvcptim                             @492      0x492a5f83
   ub2 kcvcpthr                             @496      0x0002
   union u, 12 bytes                        @500     
      struct kcvcprba, 12 bytes             @500     
         ub4 kcrbaseq                       @500      0x0000eef2
         ub4 kcrbabno                       @504      0x001a4986
         ub2 kcrbabof                       @508      0x0010


BBED> set file 3
        FILE#           3

BBED> p kcvfh.kcvfhckp
struct kcvfhckp, 160 bytes                  @484     
   struct kcvcpscn, 8 bytes                 @484     
      ub4 kscnbas                           @484      0x338943b6
      ub2 kscnwrp                           @488      0x0de1
   ub4 kcvcptim                             @492      0x491973d8
   ub2 kcvcpthr                             @496      0x0002
   union u, 12 bytes                        @500     
      struct kcvcprba, 12 bytes             @500     
         ub4 kcrbaseq                       @500      0x0000eef2
         ub4 kcrbabno                       @504      0x00000002
         ub2 kcrbabof                       @508      0x0010

然后对这些异常文件进行recover 操作

SYS@orcl1>recover datafile 3;
Media recovery complete.
SYS@orcl1>recover datafile 5;
Media recovery complete.
SYS@orcl1>recover datafile 13,18;
Media recovery complete.


Mon Nov  2 10:32:05 2026
ALTER DATABASE RECOVER  datafile 3  
Mon Nov  2 10:32:05 2026
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:07 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:07 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:07 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 3  
Mon Nov  2 10:32:16 2026
ALTER DATABASE RECOVER  datafile 5  
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:16 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:16 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:16 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 5  
Mon Nov  2 10:32:22 2026
ALTER DATABASE RECOVER  datafile 13,18  
Media Recovery Start
 parallel recovery started with 15 processes
Mon Nov  2 10:32:22 2026
Recovery of Online Redo Log: Thread 2 Group 4 Seq 61170 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro41_1g
  Mem# 1: /oracle/oradata/db_ro42_1g
Mon Nov  2 10:32:22 2026
Recovery of Online Redo Log: Thread 1 Group 2 Seq 107734 Reading mem 0
  Mem# 0: /oracle/oradata/db_ro21_1g
  Mem# 1: /oracle/oradata/db_ro22_1g
Mon Nov  2 10:32:22 2026
Media Recovery Complete (orcl1)
Completed: ALTER DATABASE RECOVER  datafile 13,18 

直接打开数据库

$ sqlplus / as sysdba

SQL*Plus: Release 10.2.0.4.0 - Production on Mon Nov 2 10:33:27 2026

Copyright (c) 1982, 2007, Oracle.  All Rights Reserved.


Connected to:
Oracle Database 10g Enterprise Edition Release 10.2.0.4.0 - 64bit Production
With the Partitioning, Real Application Clusters, OLAP, Data Mining
and Real Application Testing options
            
SYS@orcl1>set pages 10000
SYS@orcl1>set numw 16
SYS@orcl1>SELECT status,
  2  checkpoint_change#,
  3  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,
  4  last_change#,
  5  count(*) ROW_NUM
  6  FROM v$datafile
  7  GROUP BY status, checkpoint_change#, checkpoint_time,last_change#
  8  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_CHANGE# CHECKPOINT_TIME         LAST_CHANGE#          ROW_NUM
------- ------------------ ------------------- ---------------- ----------------
ONLINE      15260884095005 2026-03-10 08:02:11   15260884095005               27
ONLINE      15260884095006 2026-03-10 08:02:11   15260884095006                4
SYSTEM      15260884095005 2026-03-10 08:02:11   15260884095005                1

SYS@orcl1>
SYS@orcl1>
SYS@orcl1>set numw 16
SYS@orcl1>col CHECKPOINT_TIME for a40
SYS@orcl1>set lines 150
SYS@orcl1>set pages 1000
SYS@orcl1>SELECT status,
  2  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
  3  count(*) ROW_NUM
  4  FROM v$datafile_header
  5  GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
  6  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-03-10 08:02:11                      NO      15260884095005               28
ONLINE  2026-03-10 08:02:11                      NO      15260884095006                4

SYS@orcl1>alter database open;

Database altered.

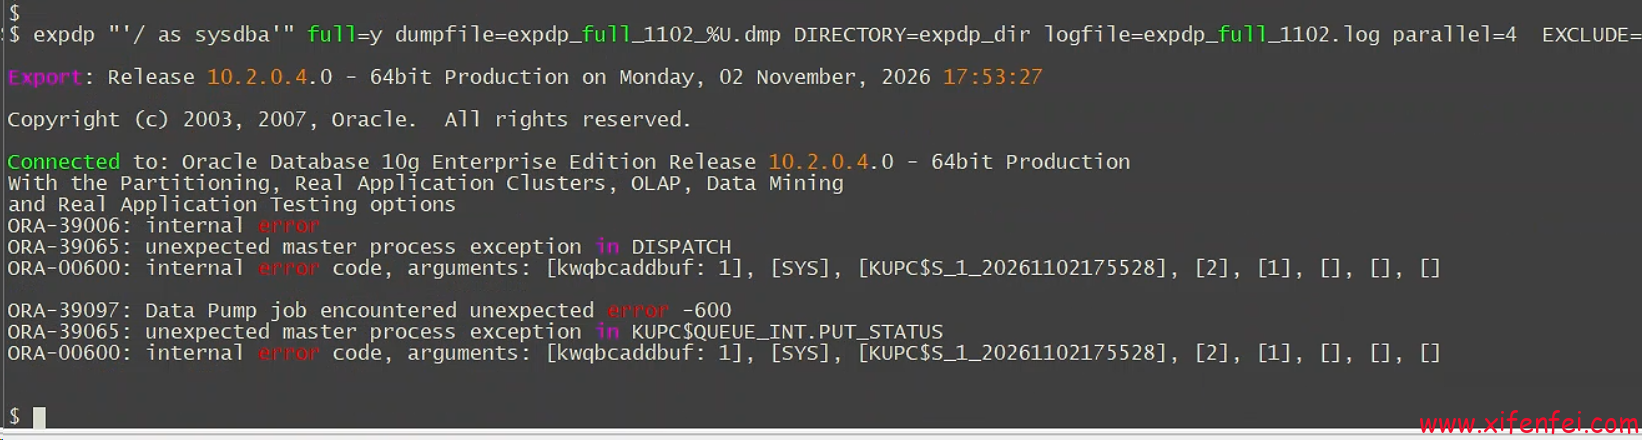
然后尝试expdp导出数据报ORA-600 kwqbcaddbuf: 1错误

$ expdp "'/ as sysdba'" full=y dumpfile=expdp_full_1102_%U.dmp DIRECTORY=expdp_dir logfile=expdp_full_1102.log
> parallel=4  EXCLUDE=STATISTICS,AUDIT

Export: Release 10.2.0.4.0 - 64bit Production on Monday, 02 November, 2026 10:38:48

Copyright (c) 2003, 2007, Oracle.  All rights reserved.

Connected to: Oracle Database 10g Enterprise Edition Release 10.2.0.4.0 - 64bit Production
With the Partitioning, Real Application Clusters, OLAP, Data Mining
and Real Application Testing options
ORA-39006: internal error
ORA-39065: unexpected master process exception in DISPATCH
ORA-00600: internal error code, arguments: [kwqbcaddbuf: 1], [SYS], [KUPC$S_1_20261102104051], [2], [1], [], [], []
ORA-39097: Data Pump job encountered unexpected error -600
ORA-39065: unexpected master process exception in KUPC$QUEUE_INT.PUT_STATUS
ORA-00600: internal error code, arguments: [kwqbcaddbuf: 1], [SYS], [KUPC$S_1_20261102104051], [2], [1], [], [], []

kwqbcaddbuf


通过rebuild datapump程序

@?/rdbms/admin/catdph.sql
@?/rdbms/admin/catmetx.sql
@?/rdbms/admin/prvtdtde.plb
@?/rdbms/admin/catdpb.sql
@?/rdbms/admin/dbmspump.sql
@?/rdbms/admin/utlrp.sql

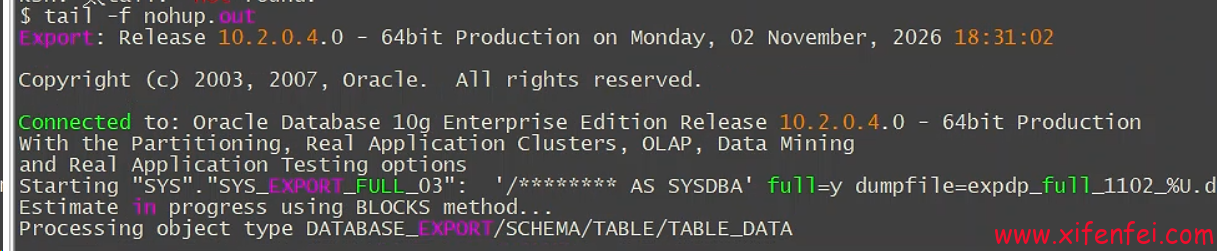
实现expdp程序可以正常导出数据
11


发表在 Oracle备份恢复 | 标签为 , , , | 留下评论

断电引起ORA-600 3005故障处理

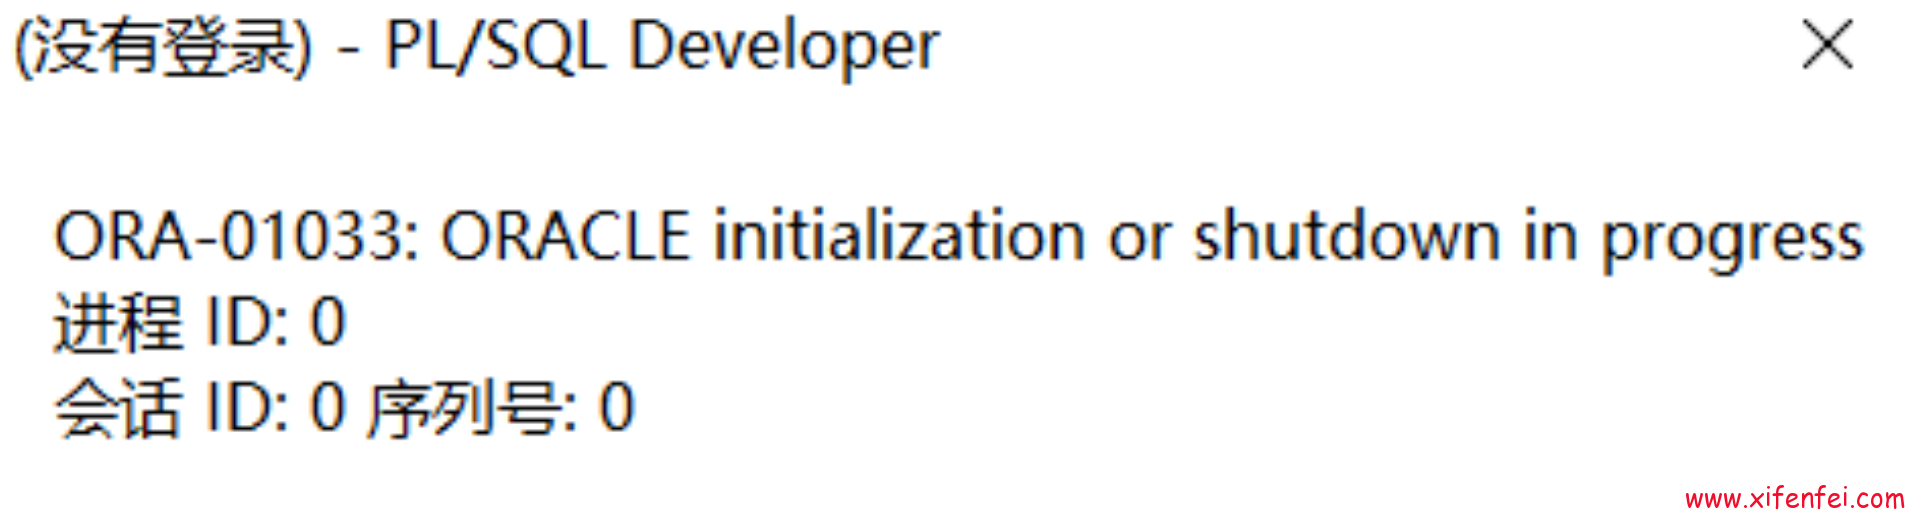
异常断电之后,客户连接数据库报ORA-01033: ORACLE initialization or shutdown in progress错误,该错误一般是由于数据库没有正常open成功导致.
ORA-01033
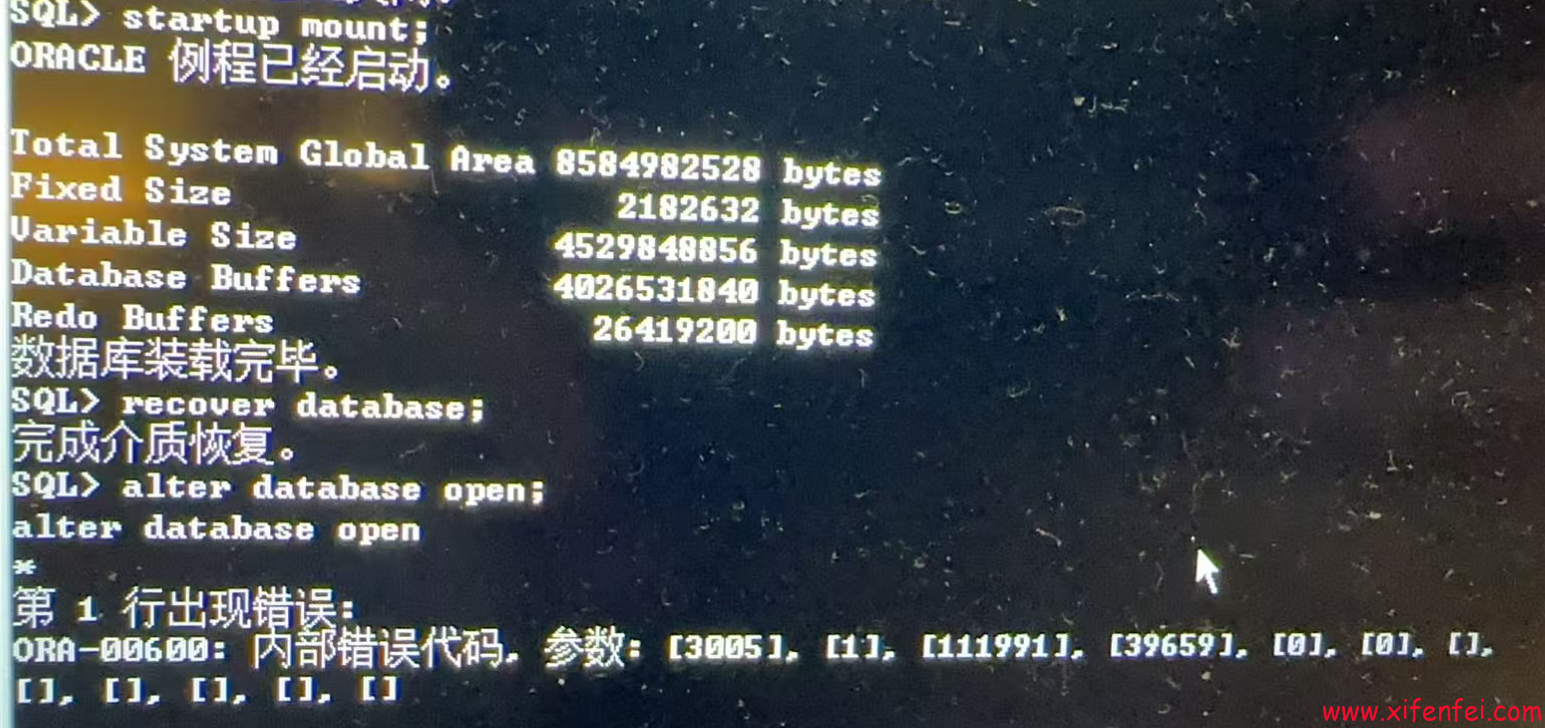
尝试人工启动数据库报ORA-600 3005错误
ORA-600-3005

Tue Oct 27 19:02:59 2026
ALTER DATABASE RECOVER  database  
Media Recovery Start
 started logmerger process
Parallel Media Recovery started with 16 slaves
Tue Oct 27 19:03:00 2026
Recovery of Online Redo Log: Thread 1 Group 3 Seq 111990 Reading mem 0
  Mem# 0: D:\orcl\REDO03.LOG
Completed: ALTER DATABASE RECOVER  database  
Tue Oct 27 19:03:22 2026
alter database open
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Started redo scan
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc  (incident=917810):
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
Incident details in: d:\app\administrator\diag\rdbms\orcl\orcl\incident\incdir_917810\orcl_ora_1908_i917810.trc
Aborting crash recovery due to error 600
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc:
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
Errors in file d:\app\administrator\diag\rdbms\orcl\orcl\trace\orcl_ora_1908.trc:
ORA-00600: 内部错误代码, 参数: [3005], [1], [111991], [39659], [0], [0], [], [], [], [], [], []
ORA-600 signalled during: alter database open...

这个错误是一个较为常见的错误,由于redo日志或者thread信息丢失导致.检查数据文件头状态一致而且干净

SQL> set pages 10000
SQL> set numw 16
SQL> SELECT status,
  2  checkpoint_change#,
  3  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,
  4  last_change#,
  5  count(*) ROW_NUM
  6  FROM v$datafile
  7  GROUP BY status, checkpoint_change#, checkpoint_time,last_change#
  8  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_CHANGE# CHECKPOINT_TIME         LAST_CHANGE#          ROW_NUM
------- ------------------ ------------------- ---------------- ----------------
RECOVER        27917313690 2026-10-27 14:51:31                                14
SYSTEM         27917313690 2026-10-27 14:51:31                                 3

SQL>
SQL>
SQL> set numw 16
SQL> col CHECKPOINT_TIME for a40
SQL> set lines 150
SQL> set pages 1000
SQL> SELECT status,
  2  to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
  3  count(*) ROW_NUM
  4  FROM v$datafile_header
  5  GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
  6  ORDER BY status, checkpoint_change#, checkpoint_time;

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-10-27 14:51:31                      NO         27917313690               17

基于这种情况,直接可以打开数据库,检测字典一致,基本上可以实现0丢失

SQL> alter database open resetlogs;

数据库已更改。

SQL> @D:/HCHECK
HCheck Version 07MAY18 on 28-10月-2026 12:20:10
----------------------------------------------
Catalog Version 11.2.0.1.0 (1102000100)
db_name: ORCL

                                   Catalog       Fixed
Procedure Name                     Version    Vs Release    Timestamp
Result
------------------------------ ... ---------- -- ---------- --------------
------
.- LobNotInObj                 ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- MissingOIDOnObjCol          ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- SourceNotInObj              ... 1102000100 <=  *All Rel* 10/28 12:20:11 PASS
.- IndIndparMismatch           ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- InvCorrAudit                ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- OversizedFiles              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PoorDefaultStorage          ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PoorStorage                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- PartSubPartMismatch         ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- TabPartCountMismatch        ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTabComPart          ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingSum$                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingDir$                 ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- DuplicateDataobj            ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjSynMissing               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjSeqMissing               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedUndo                ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndex               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndexPartition      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndexSubPartition   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTable               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTablePartition      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedTableSubPartition   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- MissingPartCol              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedSeg$                ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- OrphanedIndPartObj#         ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- DuplicateBlockUse           ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- FetUet                      ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- Uet0Check                   ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ExtentlessSeg               ... 1102000100 <= 1102000100 10/28 12:20:12 PASS
.- SeglessUET                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadInd$                     ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadTab$                     ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadIcolDepCnt               ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjIndDobj                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- TrgAfterUpgrade             ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- ObjType0                    ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadOwner                    ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- StmtAuditOnCommit           ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadPublicObjects            ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadSegFreelist              ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- BadDepends                  ... 1102000100 <=  *All Rel* 10/28 12:20:12 PASS
.- CheckDual                   ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- ObjectNames                 ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- BadCboHiLo                  ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- ChkIotTs                    ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- NoSegmentIndex              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- BadNextObject               ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- DroppedROTS                 ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- FilBlkZero                  ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- DbmsSchemaCopy              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- OrphanedObjError            ... 1102000100 >  1102000000 10/28 12:20:13 PASS
.- ObjNotLob                   ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- MaxControlfSeq              ... 1102000100 <=  *All Rel* 10/28 12:20:13 PASS
.- SegNotInDeferredStg         ... 1102000100 >  1102000000 10/28 12:20:14 PASS
.- SystemNotRfile1             ... 1102000100 >   902000000 10/28 12:20:14 PASS
.- DictOwnNonDefaultSYSTEM     ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
.- OrphanTrigger               ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
.- ObjNotTrigger               ... 1102000100 <=  *All Rel* 10/28 12:20:14 PASS
---------------------------------------
28-10月-2026 12:20:14  Elapsed: 4 secs
---------------------------------------
Found 0 potential problem(s) and 0 warning(s)

PL/SQL 过程已成功完成。

基于当前情况,客户可以直接使用当前库,实现最小损失,最快速度恢复.

发表在 Oracle备份恢复 | 标签为 , | 留下评论

记录一次云存储资源到期之后引起的数据库恢复

客户环境是运行在xx厂商上的云环境的Oracle RAC,由于其中一块asm disk资源到期没有进行续费,云厂商对该盘进行了限速(1MB/s,并且异步写入),导致运行在该rac上的数据库直接crash,客户续费之后磁盘速度恢复正常但是数据库启动报ORA-00353 ORA-00312错误(redo异常),客户找了以前的服务商进行恢复尝试没有成功.对接手后的现场进行检测,发现有20个数据文件被初始化(dbv检测全部是空块,没有写入任何表和索引数据)[直接变成了空文件,一般sqlplus中执行alter database create datafile或者在没有对应的数据文件备份的情况下执行restore datafile会出现这个情况],数据库被强制拉库,但是启动没有成功报ORA-00704 ORA-01555错误.由于客户明天领导会过来检查,所以着急启动系统,我们只能基于现在的现况给客户强制拉起来库,赌运气看看核心业务是否可以跑起来

回溯处理过程,续费欠费资源之后,数据库启动报错(估计是当时限速之后,云存储层面异步写入导致部分写丢失)

Mon Oct 26 11:38:19 2026
alter database open
This instance was first to open
Beginning crash recovery of 1 threads
 parallel recovery started with 15 processes
Started redo scan
Incomplete read from log member '+DATA/xff/onlinelog/group_3.312.1210628353'. Trying next member.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc  (incident=682004):
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
Incident details in: /oracle/diag/rdbms/xff/xff1/incident/incdir_682004/xff1_ora_19144_i682004.trc
Abort recovery for domain 0
Aborting crash recovery due to error 368
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc:
ORA-00368: checksum error in redo log block
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
Abort recovery for domain 0
Mon Oct 26 11:38:22 2026
Sweep [inc][682004]: completed
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_19144.trc:
ORA-00368: checksum error in redo log block
ORA-00353: log corruption near block 47146 change 16921129940671 time 10/26/2026 08:57:37
ORA-00312: online log 3 thread 1: '+DATA/xff/onlinelog/group_3.312.1210628353'
ORA-368 signalled during: alter database open...

屏蔽一致性,强制resetlogs的时候报ORA-00704 ORA-01555错误

Mon Oct 26 15:47:43 2026
Setting recovery target incarnation to 2
Initializing SCN for created control file
Database SCN compatibility initialized to 3
Warning - High Database SCN: Current SCN value is 16917769616373, threshold SCN value is 0
Mon Oct 26 15:47:43 2026
Assigning activation ID 2556751686 (0x9864ef46)
LGWR: STARTING ARCH PROCESSES
Mon Oct 26 15:47:43 2026
ARC0 started with pid=32, OS id=14392 
ARC0: Archival started
LGWR: STARTING ARCH PROCESSES COMPLETE
ARC0: STARTING ARCH PROCESSES
Mon Oct 26 15:47:44 2026
ARC1 started with pid=33, OS id=14446 
Mon Oct 26 15:47:44 2026
ARC2 started with pid=34, OS id=14448 
Mon Oct 26 15:47:44 2026
ARC3 started with pid=35, OS id=14450 
ARC1: Archival started
ARC2: Archival started
ARC1: Becoming the 'no FAL' ARCH
ARC1: Becoming the 'no SRL' ARCH
ARC2: Becoming the heartbeat ARCH
Thread 1 opened at log sequence 1
  Current log# 1 seq# 1 mem# 0: +DATA/xff/onlinelog/group_1.314.1210628351
Successful open of redo thread 1
MTTR advisory is disabled because FAST_START_MTTR_TARGET is not set
Mon Oct 26 15:47:44 2026
SMON: enabling cache recovery
ORA-01555 caused by SQL statement below (SQL ID: 7bd391hat42zk, SCN: 0x0f62.f9a5fbf8):
select /*+ rule */ name,file#,block#,status$,user#,undosqn,xactsqn,scnbas,scnwrp,
DECODE(inst#,0,NULL,inst#),ts#,spare1 from undo$ where us#=:1
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_13439.trc:
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_ora_13439.trc:
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Error 704 happened during db open, shutting down database
USER (ospid: 13439): terminating the instance due to error 704
Instance terminated by USER, pid = 13439
ORA-1092 signalled during: ALTER DATABASE OPEN RESETLOGS...
opiodr aborting process unknown ospid (13439) as a result of ORA-1092

从这个时候开始我接手这个故障,数据完全恢复已经不太可能,只能基于现在的情况,给客户尝试拉起来库,看看核心业务是否可以跑起来.
数据库open过程报ORA-01555错误,这个是一个比较常见的问题,以前专门写过类似文章:
在数据库open过程中常遇到ORA-01555汇总
数据库open过程遭遇ORA-1555对应sql语句补充
对于这个客户问题,我也一样尝试修改scn的方式来解决

SQL> set numw 16
col CHECKPOINT_TIME for a40
set lines 150
set pages 1000
SELECT status,
to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss') checkpoint_time,FUZZY,checkpoint_change#,
count(*) ROW_NUM
FROM v$datafile_header
GROUP BY status, checkpoint_change#, to_char(checkpoint_time,'yyyy-mm-dd hh24:mi:ss'),fuzzy
ORDER BY status, checkpoint_change#, checkpoint_time;SQL> SQL> SQL> SQL>   2    3    4    5    6  

STATUS  CHECKPOINT_TIME                          FUZ CHECKPOINT_CHANGE#          ROW_NUM
------- ---------------------------------------- --- ------------------ ----------------
ONLINE  2026-10-26 15:47:44                      YES     16917769616374              191

使用obet的patch_scn功能来修改数据库scn(obet的patch_scn功能)

OBET> patch_scn 89103 0x06001AE70 0xF62FBA5FBF6
 
=== Oracle SCN Patch ===
PID:     89103
Address: 0x06001AE70
New Value: 0xF62FBA5FBF6 (16917803170806)
Original SCN: 0x0
 
Are you sure you want to modify Oracle SCN? (yes/no): y
 
SCN modified: 0x0 -> 0xF62FBA5FBF6
Oracle SCN successfully modified.


SQL> oradebug DUMPvar SGA kcsgscn_ 
kcslf kcsgscn_ [06001AE70, 06001AEA0) = FBA5FBF6 00000F62 00000000 00000000 00000000

然后尝试打开数据库依旧报ORA-01555错误,证明我们处理的scn不正确

SQL> recover database using backup controlfile;
ORA-00279: change 16917769616374 generated at 10/26/2026 15:47:44 needed for
thread 1
ORA-00289: suggestion : +ARCH
ORA-00280: change 16917769616374 for thread 1 is in sequence #1


Specify log: {<RET>=suggested | filename | AUTO | CANCEL}
+DATA/xff/onlinelog/group_1.314.1210628351
Log applied.
Media recovery complete.
SQL> alter database open resetlogs;
alter database open resetlogs
*
ERROR at line 1:
ORA-01092: ORACLE instance terminated. Disconnection forced
ORA-00704: bootstrap process failure
ORA-00604: error occurred at recursive SQL level 2
ORA-01555: snapshot too old: rollback segment number 0 with name "SYSTEM" too small
Process ID: 18169
Session ID: 3681 Serial number: 2825

分析异常block的scn

*** 2026-10-27 01:05:42.156
Start dump data block from file +DATA/xff/system01.dbf minblk 558 maxblk 558
 V10 STYLE FILE HEADER:
        Compatibility Vsn = 186647552=0xb200400
        Db ID=2195614447=0x82de6aef, Db Name='xff'
        Activation ID=0=0x0
        Control Seq=542=0x21e, File size=446720=0x6d100
        File Number=1, Blksiz=8192, File Type=3 DATA
Dump all the blocks in range:
buffer tsn: 0 rdba: 0x0040022e (1/558)
scn: 0x0f63.c1efd2ab seq: 0x01 flg: 0x04 tail: 0xd2ab0201
frmt: 0x02 chkval: 0x75a3 type: 0x02=KTU UNDO BLOCK
Hex dump of block: st=0, typ_found=1

发现该block的scn非常大0x0f63.c1efd2ab,我之前处理的scn明显不合适,继续换上新的scn,再次打开数据库成功

OBET> patch_scn 89103 0x06001AE70 0xF64C1EFD2AB
 
=== Oracle SCN Patch ===
PID:     89103
Address: 0x06001AE70
New Value: 0xF64C1EFD2AB(16925424865963)
Original SCN: 0x0
 
Are you sure you want to modify Oracle SCN? (yes/no): y
 
SCN modified: 0x0 -> 0xF64C1EFD2AB
Oracle SCN successfully modified.


SQL> oradebug DUMPvar SGA kcsgscn_ 
kcslf kcsgscn_ [06001AE70, 06001AEA0) = C1EFD2AB 00000F64 00000000 00000000 00000000
SQL> 

SQL> 
SQL> 
SQL> alter database open;

Database altered.

后续大量异常undo问题

ORA-00376: file 182 cannot be read at this time
ORA-01111: name for data file 182 is unknown - rename to correct file
ORA-01110: data file 182: '/oracle/product/11.2.0/db_1/dbs/MISSING00182'
ORACLE Instance xff1 (pid = 20) - Error 1578 encountered while recovering transaction (21, 29) on object 99404.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-01578: ORACLE data block corrupted (file # 8, block # 1471227)
ORA-01110: data file 8: '+DATA/xff/users04.dbf'
ORACLE Instance xff1 (pid = 20) - Error 376 encountered while recovering transaction (2, 27) on object 599926.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-00376: file 211 cannot be read at this time
ORA-01111: name for data file 211 is unknown - rename to correct file
ORA-01110: data file 211: '/oracle/product/11.2.0/db_1/dbs/MISSING00211'
ORACLE Instance xff1 (pid = 20) - Error 376 encountered while recovering transaction (10, 6) on object 99591.
Errors in file /oracle/diag/rdbms/xff/xff1/trace/xff1_smon_29435.trc:
ORA-00376: file 182 cannot be read at this time
ORA-01111: name for data file 182 is unknown - rename to correct file
ORA-01110: data file 182: '/oracle/product/11.2.0/db_1/dbs/MISSING0018

由于这些文件已经被初始化掉了,恢复已经没有意义,直接没有加入到ctl中,现在主要是由于有些事务涉及这些文件,导致smon回滚的时候报这些错误,对于这样的异常,直接对于undo进行重建更换新undo即可.处理好这些问题之后,数据库open运行问题,客户自行安排业务测试和论证

发表在 Oracle备份恢复 | 标签为 , , , | 留下评论